自监督学习是与大家熟悉的监督学习和无监督学习的新名词,该类方法最早归类于无监督学习的范畴。关于自监督学习的概念,Paper with
code[1]给出的定义是,使用无标注数据用自我监督的方式学习一种表示的方法,具体方式是通过学习一个替代任务(pretext
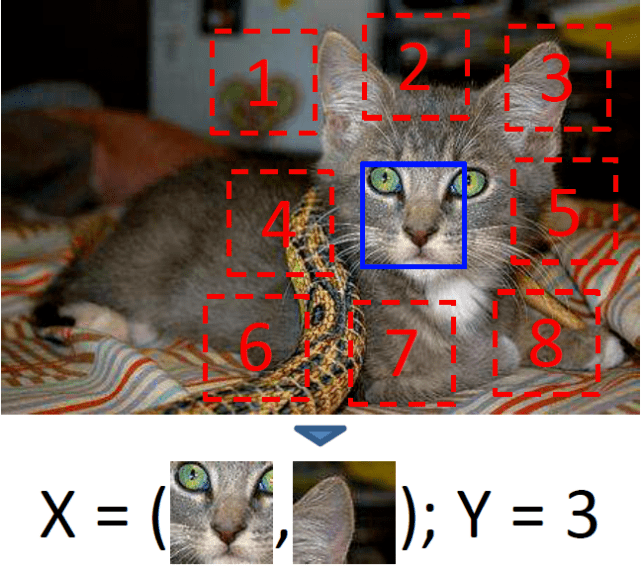
task)的目标函数来获取特征表示。替代任务可以是一个预测类任务、生成式任务、对比学习任务。替代任务的监督信息来源是从数据本身获得的。举个栗子,替代任务可以是图片上色,图片抠图位置预测,视频帧顺序预测等。或者我们从结果反推方法,对于自监督来说,数据本身是没有标签的,我们需要通过自行设计任务来确定数据的标签。例如下图[2]中把图片中扣出9个块,让模型预测每个块的位置,对每个块自动构建标签的过程就是生成标签的过程,预测位置的工作就是替代任务。
或者涅槃重生的MLP[9]等方法也可能在自监督领域大展身手,对应[9]的标题:MLP-Mixer: An all-MLP architecture for
vision,自监督下的MLP方法题目我都想好了:An all-MLP Architecture for self-supervised Learning。
[2] Doersch C, Gupta A, Efros A A. Unsupervised visual representation
learning by context prediction[C]//Proceedings of the IEEE international
conference on computer vision. 2015: 1422-1430.
[3] Chen T, Kornblith S, Norouzi M, et al. A simple framework for contrastive
learning of visual representations[C]//International conference on machine
learning. PMLR, 2020: 1597-1607.
[4] Caron M, Touvron H, Misra I, et al. Emerging properties in
self-supervised vision transformers[J]. arXiv preprint arXiv:2104.14294, 2021.
[5] Lan Z, Chen M, Goodman S, et al. Albert: A lite bert for self-supervised
learning of language representations[J]. arXiv preprint arXiv:1909.11942, 2019.
[6] Pan T, Song Y, Yang T, et al. Videomoco: Contrastive video representation
learning with temporally adversarial examples[J]. arXiv preprint
arXiv:2103.05905, 2021.
[7] Zbontar J, Jing L, Misra I, et al. Barlow twins: Self-supervised learning
via redundancy reduction[J]. arXiv preprint arXiv:2103.03230, 2021.
[8] Chen X, Xie S, He K. An empirical study of training self-supervised
visual transformers[J]. arXiv e-prints, 2021: arXiv: 2104.02057.
[9] Tolstikhin I, Houlsby N, Kolesnikov A, et al. MLP-Mixer: An all-MLP
architecture for vision[J]. arXiv preprint arXiv:2105.01601, 2021.
[10] Wang J, Jiao J, Liu Y H. Self-supervised video representation learning
by pace prediction[C]//European Conference on Computer Vision. Springer, Cham,
2020: 504-521.
[11] Wang J, Gao Y, Li K, et al. Removing the Background by Adding the
Background: Towards Background Robust Self-supervised Video Representation
Learning[J]. arXiv preprint arXiv:2009.05769, 2020.
[12] Feichtenhofer C, Fan H, Xiong B, et al. A Large-Scale Study on
Unsupervised Spatiotemporal Representation Learning[J]. arXiv preprint
arXiv:2104.14558, 2021.
[13] Hadsell R, Chopra S, LeCun Y. Dimensionality reduction by learning an
invariant mapping[C]//2006 IEEE Computer Society Conference on Computer Vision
and Pattern Recognition (CVPR'06). IEEE, 2006, 2: 1735-1742.
[14] Khosla P, Teterwak P, Wang C, et al. Supervised contrastive learning[J].
arXiv preprint arXiv:2004.11362, 2021.